
AI Search Impressions: What Exactly Is Being Counted?
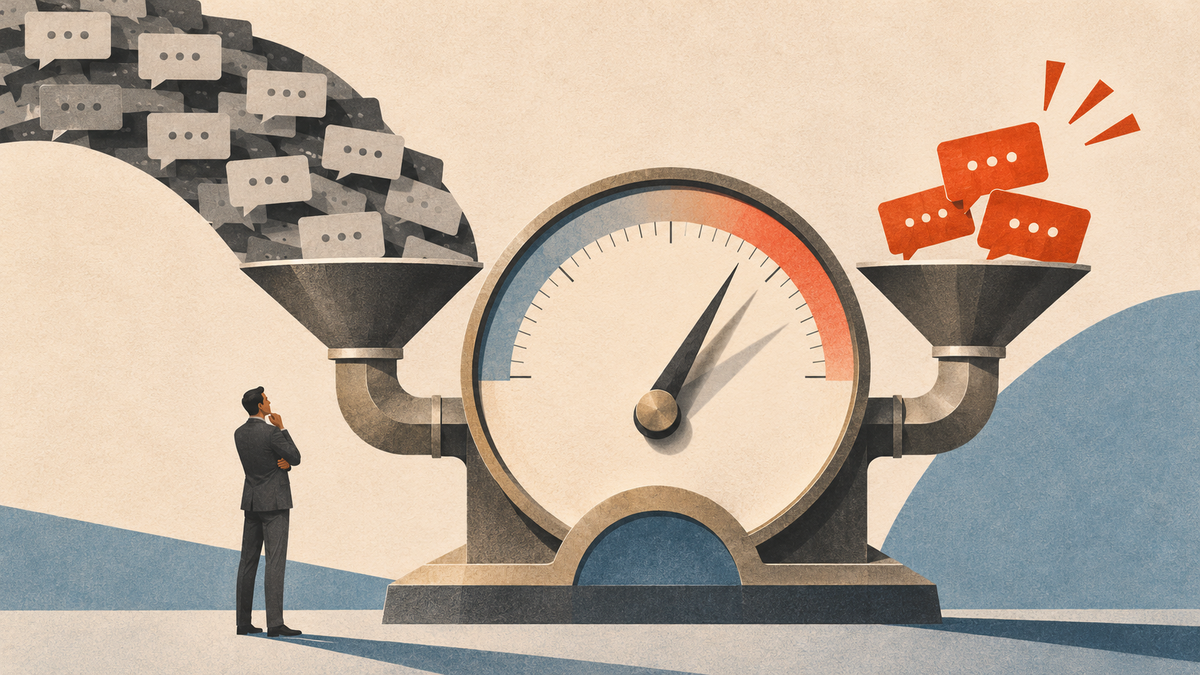
The AirOps-led proposal brings demand weighting and recommendation into AI measurement. Its value will depend on keeping exposure, choice and commercial impact distinguishable.
A brand can appear in every AI answer and still never be chosen. The proposed AI Search Measurement Standard recognises this explicitly. Its first metric gives recommendations more weight than ordinary mentions—a welcome acknowledgement that visibility alone is insufficient.
But that decision creates a question at the centre of the proposal. If the metric increases because an answer becomes more favourable, without additional exposure, what exactly has increased?
A weighted measure may be useful. Before brands use it to inform budgets, however, they need to distinguish changes in audience volume from changes in recommendation. They also need evidence that the resulting measure supports its proposed commercial uses.
A real gap, but not an empty field
The initiative, started by AirOps alongside Paramark, Chime and Hitesh Wadhwani, proposes an AI Search Impression: a weekly estimate built from buyer questions, estimated question volumes and sampled AI answers.
The problem it addresses is real. A visibility percentage has no audience denominator. Appearing in 40% of sampled answers could represent substantial exposure or very little, depending on how often buyers ask those questions.
The proposal attempts to supply that denominator. It uses opt-in panel data to estimate demand, matches messages to tracked prompts, adjusts for population differences and scales the results against public usage figures.
That is a worthwhile contribution to pursue. It is also more specific than the announcement’s assertion that AI search has “nothing comparable yet”.
Published work predates this initiative, including AIVO Standard, publicly documented in August 2025. AIVO’s corpus now includes more than 100 DOI-registered papers, with work available across Zenodo, SSRN and Academia.edu, covering visibility, recommendation, decision-stage measurement and attribution—including ATAC, the AI Traffic Attribution Convention.
These address different parts of the problem. ATAC concerns attribution conventions, rather than estimating audience exposure. A new initiative should explain where it extends, differs from or complements existing work.
The sampling guidance needs reconciliation
The report gives apparently different accounts of how many repetitions produce stable results.
One passage says most questions required about 30 runs, with some needing 41. A later table says approximately 95% of results settled within ten runs, while reporting a median of nine to fourteen. The operational default is ten repetitions per prompt.
These statements may describe different experiments, aggregation levels or tolerances. The published explanation needs to reconcile them.
Separately, it needs to define “settled”. Does that mean a specified confidence interval, a maximum change in the estimate, or another criterion?
There is no universal minimum run count that can be inferred from the description alone. The required repetitions depend on the quantity being estimated and the uncertainty considered acceptable.
Repetition also cannot repair an unrepresentative prompt sample. A precisely estimated answer to the wrong question remains the wrong measurement.
The conclusions about wording require similar restraint. The experiment covered eight checking-account questions, two platforms and US English. Evidence that first-person phrasing changed few results in those conditions does not establish that meaningful rewording rarely matters across categories, languages and platforms.
One number, two sources of change
The proposed method has three stages: define topics and select prompts; estimate how often people ask those prompts; and multiply estimated prompt volume by a composite brand score.
The third stage determines what the resulting number means.
Recommendation rate drives the composite. Positive mentions receive additional credit, while other mentions receive less. The metric therefore reflects both estimated question volume and how the brand is treated in sampled answers.
Consider a hypothetical example. Estimated demand remains at 1,000 questions, and the sampled answers consistently include the brand. Initially, they mention it neutrally. Later, they recommend it.
On the methodology described, the metric could rise even if estimated brand appearances remained unchanged. The full formula is needed to establish the size and behaviour of that effect.
The improvement may matter commercially. It represents a change in treatment, however, rather than additional exposure.
A weighted exposure measure is not inherently invalid. But its weights must be explicit, and users must be able to distinguish audience growth from stronger recommendation. Otherwise, the same increase can describe two different developments.
The report moves between describing how often buyers see a brand and how often they see it recommended. Those are related measures, but they are not interchangeable.
Reporting exposure and recommendation alongside the composite would help users interpret changes. The composite’s purpose, weighting and calibration could then be assessed on their own merits.
Recommendation needs a decision point
It would be inaccurate to dismiss this proposal as another mention counter. Its recognition that brands can be visible without being chosen is substantive.
The next question is what qualifies as a recommendation.
Inclusion among several suggested products, an initial preference and an outright final choice are different outcomes. A buyer might ask which banks to consider, explain their business, add an international payments requirement, challenge the fees and then ask which provider to choose.
A bank recommended at the opening can disappear before the decision.
The published description does not establish whether the proposed recommendation rate measures an opening answer, a later response or the final choice in a connected buying conversation.
AIVO’s decision-stage methodology carries conversations through to that choice. That does not make opening recommendations irrelevant. It means the measurement point must be identified.
Grouping prompts by topic can cover questions associated with different journey stages. It does not, by itself, reproduce a conversation in which later answers depend on earlier constraints.
A shared standard should distinguish these designs.
Weekly reporting needs a clear account of timing
The method estimates monthly prompt demand and then divides it into weeks. The report does not explain whether that division uses observed weekly activity or an allocation rule.
That matters for a metric intended to enter a weekly marketing mix model.
A series can have weekly dates without measuring actual weekly changes in demand. If a launch, seasonal event or news story produces a short burst of questions, distributing monthly volume evenly could obscure its timing.
The documentation should distinguish observed activity from allocated activity. It should also explain how uncertainty from prompt matching, population weighting, volume scaling and answer sampling reaches the final estimate.
Reporting a range is welcome. Readers need to know which uncertainties that range includes.
A model input does not establish a return on spending
The proposal acknowledges that impressions alone do not prove ROI. That qualification deserves the same prominence as the promises about informing budgets.
Providing an additive input addresses one modelling requirement. It does not establish that a model can reliably identify incremental commercial impact.
Existing brand demand may influence both AI recommendations and sales. Advertising, publicity, product changes and distribution may affect both as well. The analysis must distinguish AI’s contribution from the demand and activity that helped produce the AI answer.
There is a further distinction that matters directly to marketing budgets:
Estimating the contribution of AI exposure is not the same as estimating the return on spending to improve AI performance.
The latter requires evidence that the intervention changed the AI outcome, as well as evidence connecting that change to commercial performance.
A number that fits into a model does not complete that chain. Disclosed validation, controls and sensitivity analysis are needed to assess how much confidence a budget decision deserves.
What would make this a useful standard?
The proposal makes several constructive moves: grounding prompt selection in observed behaviour, weighting questions by estimated demand and recognising that recommendation differs from mention.
Its next task is to preserve the distinctions that make the results interpretable:
| Measure | Question |
|---|---|
| Exposure | How often does a brand appear? |
| Recommendation | Does the assistant select it, and at which decision point? |
| Attribution | How are observed visits and actions credited? |
| Incrementality | What happened because of the activity that would otherwise not have happened? |
These measures can inform one another. Combining them does not remove the need to define each one.
The initiative describes its work as a starting point, with full calculation documentation forthcoming. It should be assessed as a developing proposal whose assumptions and performance remain open to examination.
AIVO’s methods should face the same scrutiny. Publication creates an inspectable record; a DOI provides a persistent reference. Neither substitutes for validation, independent assessment or adoption.
The next release should publish the composite formula and weights, define what counts as a recommendation, reconcile the repetition findings, explain the weekly allocation and disclose results from validation in marketing mix models. Those details will let brands judge what the number measures and which decisions it can support.
Disclosure: AIVO publishes AIVO Standard and provides commercial AI measurement and agentic commerce services. This article assesses the initiative’s published methodological description, rather than independently validating its underlying data or results.
Read the AI Search Impressions proposal · Explore AIVO Standard
Comments ()