
The Machine That Chooses
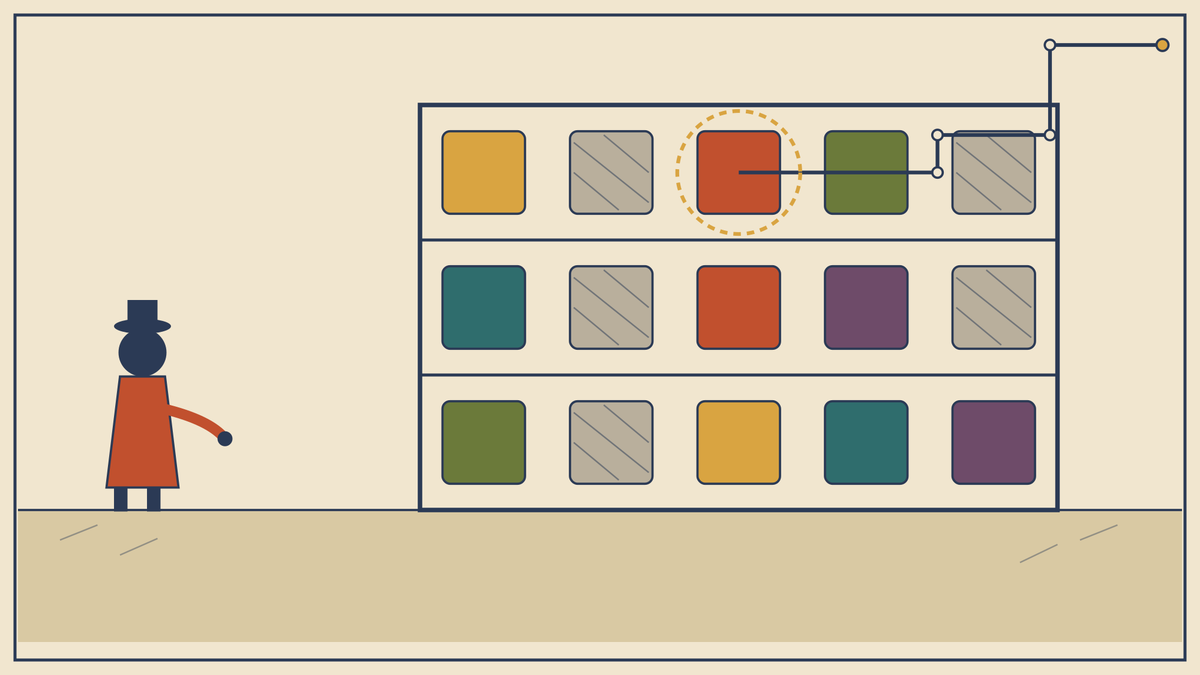
A shopper standing in front of a supermarket shelf rarely conducts the kind of deliberation marketers like to imagine.
Decades of consumer research, from Kahneman and Tversky through Byron Sharp and the work that followed, suggest that much of brand choice depends on memory structures, contextual cues, mental availability and simple heuristics rather than an exhaustive comparison of every available alternative.
A consumer carries a relatively small set of brands into a buying situation, retrieves those that come to mind, and makes a choice from that set. Deliberation certainly occurs, particularly for consequential purchases, but it is not the universal mechanism of consumer choice.
Large language models introduce something new into that process. Ask ChatGPT, Gemini or another conversational AI, "What's the best moisturizer for sensitive skin?" or "Which bank should I use for a small business?" and the system does not present the consumer with the entire market. It produces a finite answer set, and that distinction matters more than it first appears, because the important question is no longer simply whether a model knows a brand. It is whether the brand survives long enough in the interaction to become part of the decision.
Our research at AIVO examines precisely this transition. Across thousands of multi-turn probes, we have observed that a brand can be recognised, mentioned and supported with apparently relevant evidence early in a conversation, yet disappear before the model reaches its recommendation.
We have mapped fifteen distinct reasoning paths through which models move from an initial candidate set toward a recommendation. These paths differ, but they share a common characteristic: the model progressively narrows the field rather than comparing the entire market on every turn.
That creates a different kind of visibility problem. A brand that never enters the relevant candidate set cannot compete at the recommendation stage. A brand that enters but fails to survive the model's criteria can be mentioned without being recommended. A brand that reaches the recommendation stage can still fail to become the consumer's final choice.
We describe the broader discontinuity as the Linkage Gap, the distance between being known by a model and being connected to the decision it ultimately produces. This distinction is easy to miss because conventional AI-visibility measurement tends to stop too early. A citation, mention or retrieval event demonstrates that a model has access to information about a brand. It does not demonstrate that the information survives the decision process, which is why AIVO's own headline measure, the AI Recommendation Quotient, is built to track survival through that process rather than mere presence at the start of it.
The retail analogy is useful but has a limit. A shopper walking past a supermarket shelf can discover something unexpected. A brand that was not previously salient can still attract attention through packaging, placement, price or simple happenstance. The physical environment contains opportunities for surprise. A conversational model has no obligation to surface every available alternative, and if a brand is absent from the model's answer set, the consumer may never know it was an option. That changes the economics of brand competition. The machine is increasingly participating in the construction of the consideration set.
The new gatekeeper
This is where the subject intersects with AI governance. The most visible AI-safety debate concerns increasingly capable systems: whether they can be controlled, whether their objectives remain aligned with human intentions, whether their reasoning can be understood, and what happens when their capabilities exceed our ability to predict their behavior. Those questions are fundamental.
A parallel governance problem is already observable at consumer scale, because AI systems increasingly sit between people and decisions. Which product should I buy. Which bank should I use. Which software should my company adopt. Which hotel should I book. Which university should I consider. Which clinic should I visit. In each case, the model can influence which alternatives a person sees before the person makes the decision.
The consumer remains the decision-maker. The model's output is one input into the process, and large language models are fundamentally different computational systems from human minds. The functional parallel is what matters: both can operate on a reduced candidate set rather than considering every possible alternative, and what enters that set can have disproportionate consequences for what ultimately gets selected.
The difference is that the model's candidate-generation and elimination processes are largely invisible to the person receiving the answer. Interpretability research has made real progress, but a reliable, general-purpose explanation of individual commercial recommendations remains beyond what external observers can currently obtain. Much of what we know about AI-mediated brand choice therefore comes from behavioral observation rather than direct access to a model's internal reasoning. That is a measurement problem before it is anything else.
From shelf placement to answer placement
Retailers have spent decades making physical distribution measurable. Brands can measure shelf position, availability, distribution, pricing, promotional placement and sales. Regulators can examine market structures and commercial incentives. Researchers can observe what happens at the point of purchase. The equivalent measurement layer for AI-mediated choice is still immature.
We can observe the output, systematically probe the system, compare brands across prompts, platforms and turns, and record which brands are introduced, which survive, which disappear and which ultimately receive the recommendation. What we cannot reliably do is open a model and inspect a single causal chain explaining why one brand survived while another did not.
That distinction changes how the evidence should be interpreted. A repeated behavioral pattern can establish that something is happening without establishing the complete internal mechanism producing it, and the appropriate response to that limitation is systematic observation rather than premature certainty.
Nielsen transformed aspects of retail competition by making previously opaque behavior measurable. Share, distribution, penetration and purchasing behavior could be observed at scale and compared across markets. AI-mediated choice needs an equivalent discipline, and the relevant unit is no longer simply the mention. It is the decision journey.
A brand can first be mentioned, then become one of the candidates under active consideration, then receive an explicit recommendation, and finally be chosen by the human user. Those are four different events, and a brand can be highly visible and still lose the recommendation. It can be frequently cited and still disappear when the criteria become more demanding. It can win the recommendation and still fail to generate the purchase.
That is why "cited isn't chosen" describes more than a limitation of an existing measurement category. It identifies a structural feature of AI-mediated commerce: visibility is upstream, choice is downstream, and the further downstream the measurement moves, the more commercially consequential the question becomes.
What happens when the machine becomes the shelf
The significance extends beyond marketing. If conversational AI becomes a primary interface through which people discover products, services and institutions, the organizations controlling those systems will occupy a position analogous to a powerful intermediary. A retailer controls a physical or digital shelf through explicit commercial mechanisms.
A model generates responses through a combination of training data, system design, retrieval mechanisms, model behavior, user context and other technical factors, and different models can produce radically different consideration sets for the same question. That makes the problem less transparent, not more, because a model does not need an intention to favor one company for a commercially consequential selection to emerge.
The selection can arise from nothing more than the interaction of data, system design, context and model behavior, and the resulting asymmetry is significant. The brand knows it lost. The consumer sees the recommendation. Neither necessarily knows precisely why the alternative disappeared three turns earlier.
Measurement before intervention
There is an obvious temptation to turn this into another optimization discipline: determine what the model prefers, then manipulate the inputs until the model prefers you. That would miss the deeper point. Before organizations can responsibly optimize for AI-mediated choice, they need to understand what is actually happening.
Which brands are entering the candidate set. Which attributes cause them to survive or disappear. Which competitors replace them. At what point in the conversation does the loss occur. Does the same pattern appear across models, and does it persist across repeated trials. Can the observed behavior be reproduced. These are measurement questions before they are marketing questions, and our work at AIVO is built around that distinction.
The objective is to follow the decision journey far enough to observe where a brand survives, where it loses, and what observable criteria appear associated with that outcome. The result is not an explanation of everything happening inside a model. It is a behavioral record of what happens at the interface between the model and the decision, and that record is already commercially useful on its own terms.
The machine does not need to think like us
The most consequential development may have little to do with whether machines think like humans. They do not. The significance comes from the position they occupy in the decision process. A growing number of human decisions are now preceded by machine-generated consideration sets, and when that happens, access to the consideration set becomes economically consequential in its own right. A brand that is absent from the set has no opportunity to argue its case.
A brand that enters but repeatedly fails the model's criteria faces a different problem, one of survival rather than access. A brand that wins the model's recommendation but fails to convert the human user faces a third problem again, one of persuasion rather than either access or survival.
These are different failures occurring at different points in the same journey, which is why the next generation of AI measurement should move beyond asking whether a machine can see a brand. The more consequential question is whether the machine carries that brand forward into the decision, and eventually, whether the human does.
The machine does not have to replace the consumer to change consumer choice. It only has to decide what the consumer gets to consider.
Comments ()